
Posts
24
Jul
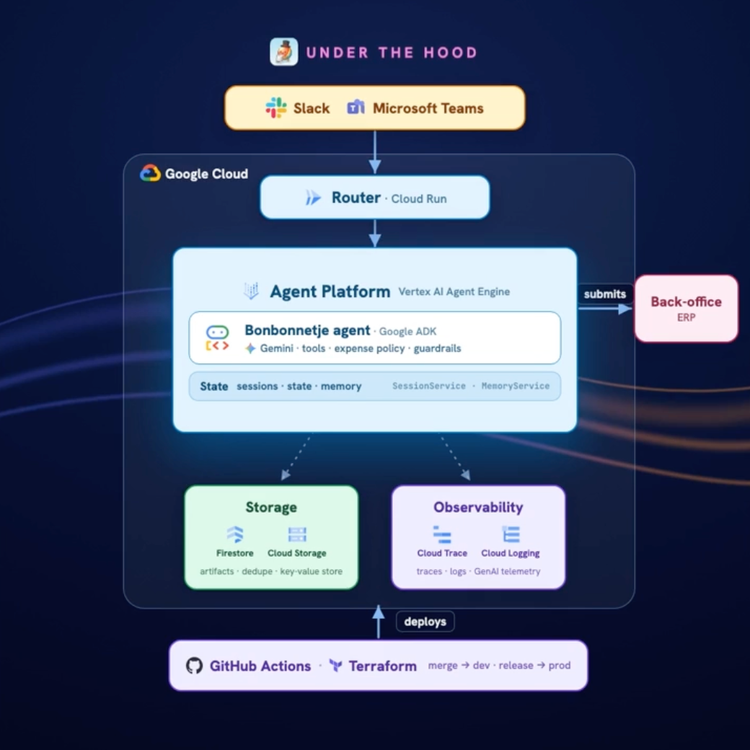
Our internal AI agent for expenses: Bonbonnetje 🍬
Bonbonnetje is an AI Agent running in production on Agent Platform helping Xebians submit expense claims. Bonbonnetje is in active use by multiple internal departments and successfully completes hundreds of submissions monthly, helping save both employees and back-office valuable time.
5 min read
25
Nov
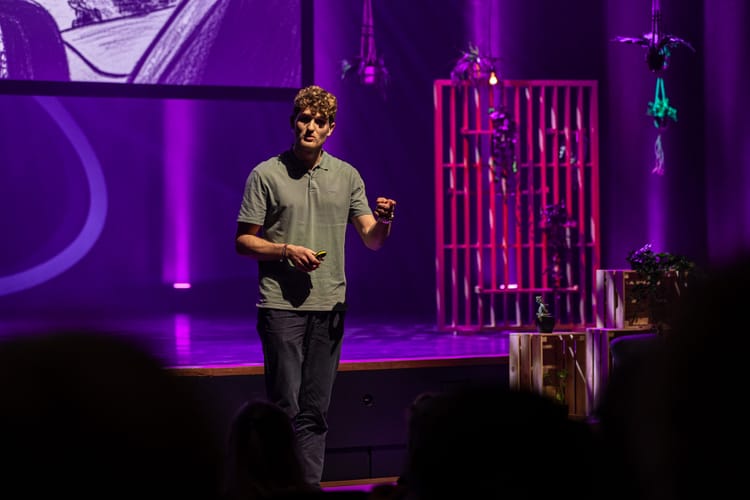
TEDXKE 2025
Amersfoort, The Netherlands —
TED-style Xebia knowledge sharing session (XKE) in the Flint theatre in Amersfoort, sharing experiences on a three month working engagement at a health-tech company in Kenya.
1 min read
03
Oct
Fine-tuning LLMs yourself
Fine-tuning can be a powerful way to specialised Large Language Models (LLMs). With open source models readily available, it is now also possible to fine-tune yourself. Read along to find out how.
7 min read
02
Oct
Python Devcontainer with uv
Devcontainers are very powerful. So is uv. How do we combine the two?
5 min read
17
Jul
Are you ready for MLOps?
MLOps has survived the hype cycle and is gaining in maturity. But are we looking at MLOps for answers for the right things? When should you even start thinking about MLOps, or when is ‘plain’ DevOps wiser to focus on first?
9 min read
09
Apr

The GenAI automation potential of data extraction
GenAI has been around for a little while and its capabilities are expanding quickly. But still, many companies fail to generate actual value with GenAI. Why is that? In this blogpost, we explore the GenAI automation potential that exists today for data extraction.
10 min read
27
Sep
The Levels of RAG
LLM’s can be supercharged using a technique called RAG, allowing us to overcome dealbreaker problems like hallucinations or no access to internal data. But what can we expect from RAG? What use cases work well and which are more challenging? Let’s find out together!
15 min read
11
Jul
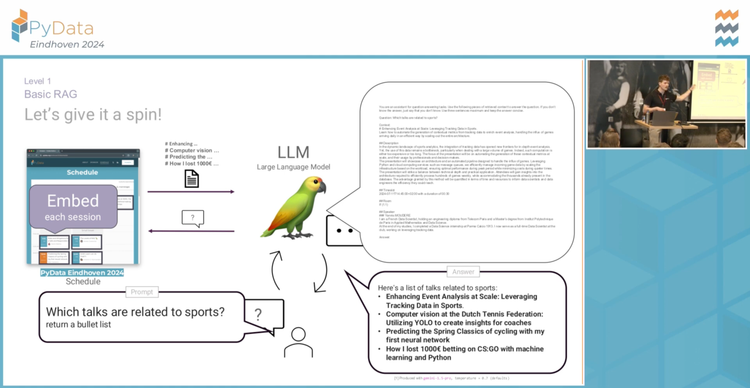
PyData Eindhoven 2024
Eindhoven, The Netherlands —
Retrieval Augmented Generation (RAG) is powerful. Let's go from Basic (chunking, vector embeddings, nearest-neighbor search) to Hybrid Search (TF-IDF, BM-25 and Reciprocal Rank Fusion) to Advanced (PDF parsing, tables, graphs) and finally, the cutting edge: Multimodal.
16
Jun
PyData London 2024
London, United Kingdom —
MLOps takes the best of DevOps and applies it to operationalizing ML, introducing concepts like experiment tracking, dataset versioning, model registries, ML pipelines, CI/CD and better observability. But MLOps goes beyond just tech- MLOps is also about People and Process.
14
May
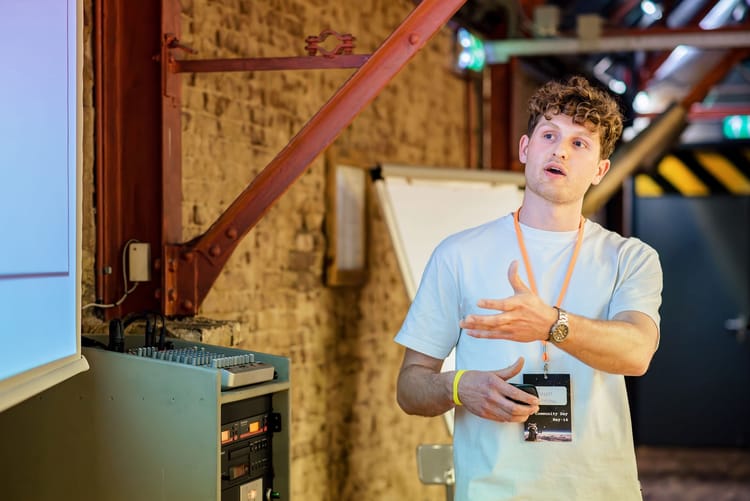
AI Community Day 2024
Utrecht, The Netherlands —
LLMOps on Azure: scaling RAG applications, using Azure AI Search (keyword and vector search, reciprocal rank fusion), hosting LLM apps on Azure Container Apps, IaC with Terraform, robust CI/CD setups and an elaborate observability stack with Langfuse/OpenTelemetry.
2 min read
26
Mar
RAG on GCP: production-ready GenAI on Google Cloud Platform
GCP has an increasing set of managed services that can help you build production-ready Retrieval Augmented Generation (RAG) applications. How can you best leverage them to build RAG applications? Let’s explore together. Read along!
6 min read
16
Mar
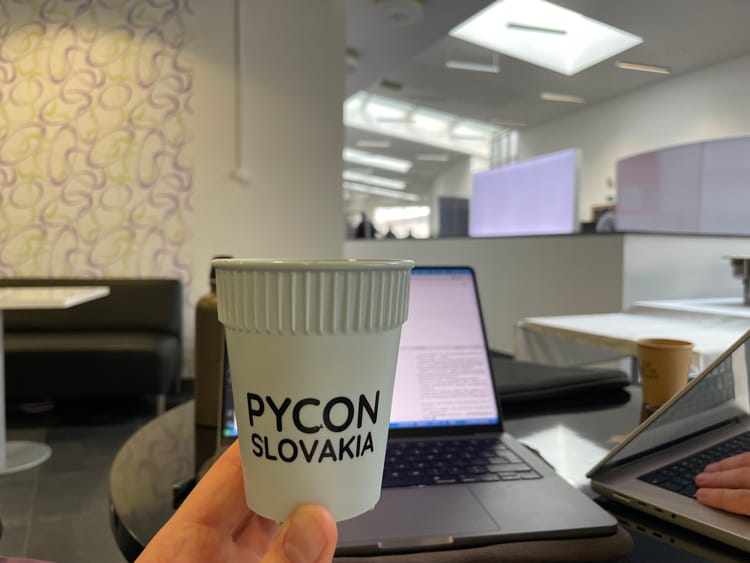
PyCon SK 2024
Bratislava, Slovakia —
What are the prerequisites you need before you can properly adopt MLOps? Let's learn together: why MLOps, what it is, how it relates to DevOps- and how you can best adopt it.